On September 1, 2026, the U.S. Department of Justice filed a position before a federal court in New York in favor of OpenAI and Microsoft in their lawsuit against the New York Times. The heart of the debate is fair use, a concept in American law that may allow certain transformative uses of protected works without prior licensing.
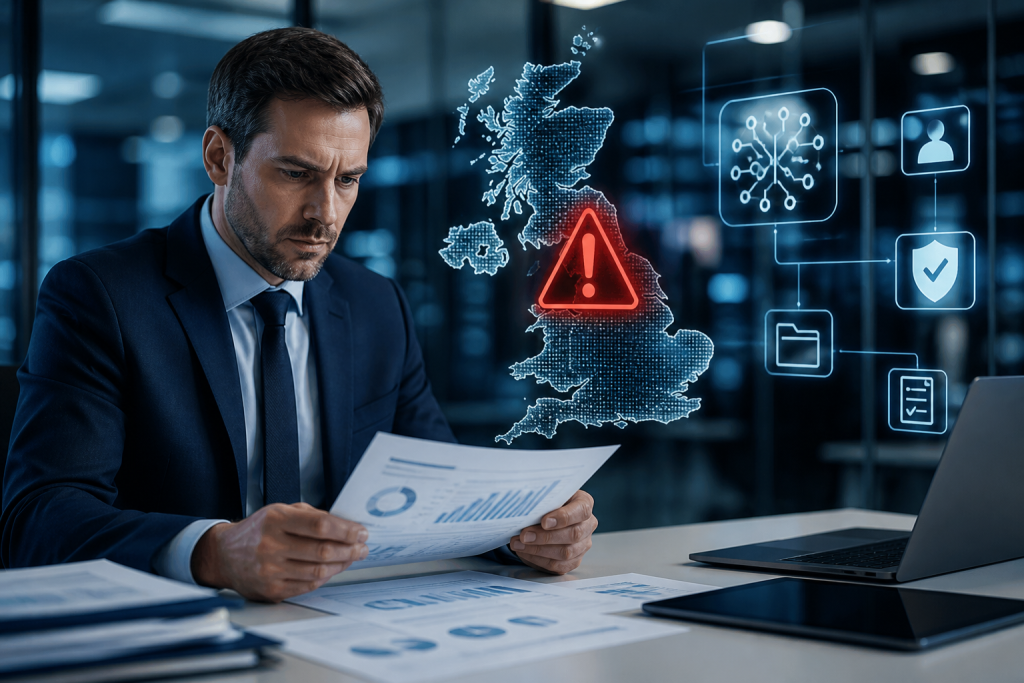
The professional stakes go beyond the press: companies, law firms, universities, and administrations are already using artificial intelligence (AI) to produce notes, contracts, summaries, or analyses. In Libreville, a corporate lawyer who asks a tool to summarize OHADA (Organization for the Harmonization of Business Law in Africa) contracts must therefore verify what is exploitable, confidential, and legally safe.
Recent articles
Hexagon acquires Rocscience: geotechnics under data
Rio Tinto accelerates five mining startups, the proof remains to be seen
Offshore: Oxy and Valaris awarded, HSE AI must remain human
 Certificate
Professional Certificate in Energy Law
What is it, concretely?
To create a generative AI like ChatGPT, a company trains its systems on very large volumes of texts. Some may be protected by copyright: articles, books, archives, commented decisions, standard contracts, or professional documents. Before reusing protected content, an organization often had to obtain a license or identify a legal exception. Here, the U.S. government tells the judge that training an AI can be transformative enough not to be automatically illegal.
The key point: this position is neither a law, nor a regulation, nor a definitive judicial victory for OpenAI. Judicial and media sources describe a procedural act in a private litigation. The judge will still have to assess the facts. Above all, this does not resolve other risks: data provenance, possible reproduction of protected passages, confidentiality of documents sent to the tool, personal data protection, and applicable law outside the United States.
Concrete case: what to do and what not to do
Questions to Ask Before Acting
- If our organization uses an AI trained or fed by protected content, who bears the legal risk: the provider, us, or both?
- Does what this case changes in our profession represent a mere technical possibility, or an obligation for documentary and contractual governance?
- Do the documents sent to the tool contain personal data, business secrets, HR information, or elements covered by professional secrecy?
- Have we understood the provider's clauses on data retention, reuse, deletion, and location?
- Are the produced responses verified by a lawyer, tax advisor, HR manager, or competent professional before external use?
- Do our contracts with clients allow the use of AI tools and specify confidentiality limits?
- In case of a dispute, can we explain how the note, contract, or decision was produced, reviewed, and validated?
UNIVGA Viewpoint
Sources
- Associated Press, Trump administration backs OpenAI in New York Times copyright case
- Agency, DOJ Tells Court AI Training on Copyrighted Text Is Fair Use
- Justia, The New York Times Company v. Microsoft Corporation et al.
- U.S. Copyright Office, Copyright and Artificial Intelligence, Part 3
- DataReportal, Digital 2026: Gabon
- APDPVP, Authority for the Protection of Personal Data and Privacy
 French
 English